nopecha.com/demo/cloudflare
Cloudflare · Request times879ms TRAWL · best repeat
TRAWL879ms
FlareSolverr12.3s
Byparr18.5s
A fast, self-hosted scraping engine that starts with HTTP and only opens a browser when the page needs it. Solve supported challenges, reuse accepted sessions and get the content without repeating the expensive work. Use the API, connect an AI agent through MCP, or plug it into Prowlarr. Less waiting. Less browser work. More useful pages.
capabilities
APIs for applications, MCP for agents, browser sessions for repeat work and a dashboard for everything TRAWL handles.
Start with HTTP and reuse accepted Cloudflare or Anubis clearance without opening a page. Escalate to browser solving and an optional residential proxy when needed.
Read Markdown or text, scrape HTML, extract JSON records, capture screenshots and inspect browser activity. Connect any Streamable HTTP MCP client to known public URLs.
Keep cookies, localStorage and sessionStorage across native, MCP and FlareSolverr-compatible requests. Sessions have capacity and idle limits and can be invalidated under memory pressure.
Persistent request history, winning tiers, failure causes and timings at /dashboard. Live updates and JSON export, with stored URLs limited to domains.
Provider-specific handling for Cloudflare, Akamai, Imperva, DDoS-Guard, AWS WAF, DataDome and Anubis. Persistent walls are reported as failures.
Turnstile, reCAPTCHA v2 audio, hCaptcha auto-pass/audio, GeeTest Slide, ALTCHA, Friendly Captcha and CAP. Support depends on the widget variant.
Paid fallback for supported declarative reCAPTCHA v2/Enterprise and standalone Turnstile. Other catalogue tasks use hostname-specific profiles; disabled by default.
Forward ordinary traffic directly. Detected walls use the same scraping tiers. WebSockets, binary streaming and Range requests retain direct proxy semantics.
Firefox with fingerprint patches at the C++/Juggler level. Browser identity and solved domain sessions can be reused when the target accepts them.
Shared deadlines, cancellation cleanup, crash recovery and memory-aware recycling. Start with one warm browser; optional idle retirement and ad-blocking controls tune the workload.
Wait for visible content, extract CSS-selected records and capture a viewport, full page or element. Native requests can also collect bounded network and console diagnostics.
Connect Prowlarr or Jackett through the familiar request and session API. Point your integration at TRAWL and keep your existing indexer configuration.
how it works
TRAWL starts with the cheapest eligible path and escalates when needed. Accepted clearance sessions can avoid a fresh solve. A shared request deadline bounds fetching, browser work and captures.
Fetch ordinary content directly, or replay accepted Cloudflare and Anubis clearance with the matching browser identity. No new browser page is needed when HTTP is accepted.
Restores solved cookies from Redis into a warm pooled browser. No challenge re-solve while the target accepts the session. Cache TTL is configurable; rejected sessions escalate.
A fresh Camoufox context runs the matching challenge flow, including Cloudflare and Anubis. Supported embedded widgets use their own solver and completion checks. Cookies are cached on success.
Same as Tier 3 but routed through a residential proxy. Only triggered after the direct or datacenter path fails, so paid residential bandwidth is used only when necessary.
benchmarks
Real sites behind Cloudflare interstitials, tested through the same API. Reuse accepted sessions and get the page content without repeating the expensive work.
879ms TRAWL · best repeat
85ms TRAWL · best repeat
473ms TRAWL · best repeat
First visits and accepted-session repeats. Only verified page content counts; best times vary by site and connection.
Same machine and network. CPU compares requests completed by every tool; RAM covers the full test. TRAWL includes Redis. Full measurements ↗
Green: included. Orange: a different or more limited approach. Muted: no dedicated functionality.
| capability | TRAWL | FlareSolverr | Byparr |
|---|---|---|---|
| Adaptive routing | ✓HTTP → cache → browser → residential | ✗ Browser only | ✗Browser only |
| Challenge proxy | ✓HTTP/S, WebSockets, Range | ✗ API only | ✗API + web loader |
| Proxy escalation | ✓Automatic fallback to a residential proxy | ~ Manual proxy selection | ~Manual proxy selection |
| Domain clearance cache | ✓Accepted sessions cached by domain | ~ Explicit named sessions | ✗No shared domain cache |
| Warm browser pool | ✓Configurable pool; one browser by default | ~ Temporary or named-session browsers | ✗Browser created per request |
| Pool recovery | ✓Health checks, recycling and crash recovery | ✗ No shared warm pool | ✗No shared warm pool |
| Target request headers | ✓Custom headers across all scraping tiers | ✗ Parameter deprecated; not forwarded | ✗No target-header field |
| Browser sessions | ✓Native, MCP and /v1; domain cache | ~ Permanent /v1 sessions | ~FlareSolverr-compatible request API |
| Browser engine | ✓Camoufox Firefox | ✓ Chrome + undetected-chromedriver | ✓InvisiblePlaywright |
| Native MCP | ✓Six Streamable HTTP MCP tools | ✗ Not documented | ✗Not documented; Open WebUI loader |
| Local dashboard | ✓Persistent metrics and live history | ✗ No documented dashboard; Prometheus metrics | ✗Not documented |
| Page outputs | ✓HTML, Markdown, CSS-selected JSON, screenshots | ~ HTML, cookies and screenshots | ~HTML, cookies and Open WebUI loader |
| Dedicated challenge flows | ✓Cloudflare, Akamai, Imperva, Anubis and more | ~ Cloudflare and DDoS-Guard | ~Cloudflare interstitial and Turnstile |
| Paid solver | ✓Local first; optional 2Captcha | ~ Not required for browser solving | ~Not required for browser solving |
challenge coverage
Detect the protection, run the matching browser flow and check that it cleared. Built-in solvers handle supported challenges without a paid service; optional 2Captcha support adds another route when needed.
| challenge / CAPTCHA | local solving | optional 2Captcha |
|---|---|---|
| Browser protection | ||
| Cloudflare interstitialJavaScript interstitials and managed challenges | Built-inBrowser JS, Turnstile interaction and clearance recovery | ProfileSite profile for supported Turnstile challenges |
| Akamai Bot ManagerSensor checks and press-and-hold challenges | Built-inSupported sensors and press-and-hold flows | Not offered |
| Imperva / IncapsulaSensor cookies and interactive CAPTCHA walls | PartialSensor-cookie flow; own interactive CAPTCHA unsupported locally | ProfileSite profile required |
| DDoS-GuardJavaScript checks and clearance cookies | Built-inJavaScript challenge and cookie recovery | Not offered |
| AWS WAFSilent token challenges or a visual CAPTCHA | PartialToken challenge; interactive CAPTCHA detected separately | ProfileSite profile for CAPTCHA |
| DataDomeDevice Check, slider CAPTCHA and IP blocks | PartialDevice Check with the opt-in headful pool; slider and hard-block detection | ProfileSite profile for slider CAPTCHA |
| CAPTCHA widgets | ||
| Turnstile widgetEmbedded checkbox and invisible widgets | Built-inShadow-DOM/frame interaction and response-token checks | AutomaticAutomatic fallback for supported declarative widgets |
| reCAPTCHA v2Checkbox verification with audio fallback | Built-inCheckbox and audio solving | AutomaticAutomatic fallback for supported declarative widgets |
| reCAPTCHA Enterprise / v3Enterprise v2 widgets and score-based v3 | External onlyNo dedicated built-in solver | Automatic / profileDeclarative v2 Enterprise fallback; profiles for v3 |
| hCaptchaAuto-pass, audio or an interactive image grid | PartialAuto-pass and audio where offered; no image-grid solver | Not offered |
| GeeTest SlideDrag a puzzle piece into position | Built-inPuzzle matching with verified-state checks | ProfileSite profile required |
| Proof of work | ||
| ALTCHA / Friendly CaptchaCryptographic work performed in the browser | Built-inNative widget execution and response checks | ProfileSite profile required |
| CAP proof of workLightweight, self-hosted CAPTCHA widgets | Built-inNative widget execution; verifies all visible widgets | Not offered |
| AnubisBrowser proof of work before the real page loads | Built-inNative JS proof of work and metarefresh handling | Not offered |
| Other detected walls | ||
| DuckDuckGo anomaly wallImage-selection verification on search traffic | Detected onlyDetected as CAPTCHA-required; no local image-puzzle solver | Not offered |
DataDome needs BROWSER_HEADFUL_POOL_SIZE=1, which adds a browser pool. IP blocks can require a different egress IP. A detected challenge or widget token does not guarantee target-server acceptance. See supported flows and limits.
Arkose/FunCaptcha, Capy, KeyCaptcha, Lemin, CyberSiara, MTCaptcha, CutCaptcha, ATB, Tencent, Prosopo, CaptchaFox, VK, Yidun, Binance, Hunt, TSPD, Basilisk, Alibaba and Yandex SmartCaptcha.
Profiles also support image/text/audio, rotation, coordinates, grids, drawing, bounding boxes, drag-and-drop, Temu, SmartCaptcha image, Pazl and VK image tasks. Each profile supplies task inputs, response delivery and verification for one exact hostname. SDK markers alone never start a paid task.
2Captcha is disabled by default and requires an API key and credit. Profiles connect supported tasks to a specific site's widget and verification flow. Configure the external solver.
challenge-aware proxy
Enable MITM_ENABLED=true and point your HTTP-compatible client at port 8192. Normal traffic takes the direct path; detected challenge pages automatically escalate through TRAWL's browser solver and return the resolved response.
curl --cacert trawl-ca.crt --proxy http://localhost:8192 https://nopecha.com/demo/cloudflareHTTPS interception requires the generated TRAWL CA certificate to be trusted by the client. installation guide ↗
MCP for AI agents
Connect a Streamable HTTP MCP client to the same challenge-aware engine your applications use. Load a known public URL, then choose the output your workflow needs.
readMain content as Markdown or text. Raw TXT, JSON and XML stay intact.
scrapePage HTML with final URL, tier timings and scrape metadata.
extractCSS-selected JSON records, with optional JavaScript rendering and readiness.
screenshotViewport, full-page or selected-element JPEG captures.
inspectBrowser console, network activity, redirects and timings.
scrape_urlCompatibility alias for scrape.
connect once
MCP_ENABLED=true

Transport: Streamable HTTP
URL: http://localhost:8191/mcp
Works with clients that support remote MCP servers. Keep the endpoint on a private network. TRAWL loads URLs; search discovery belongs to your search provider.
MCP setup and tools ↗local observability
See what TRAWL handled, which tier succeeded and why a request failed. Persistent SQLite history survives container replacement when you mount the metrics volume.
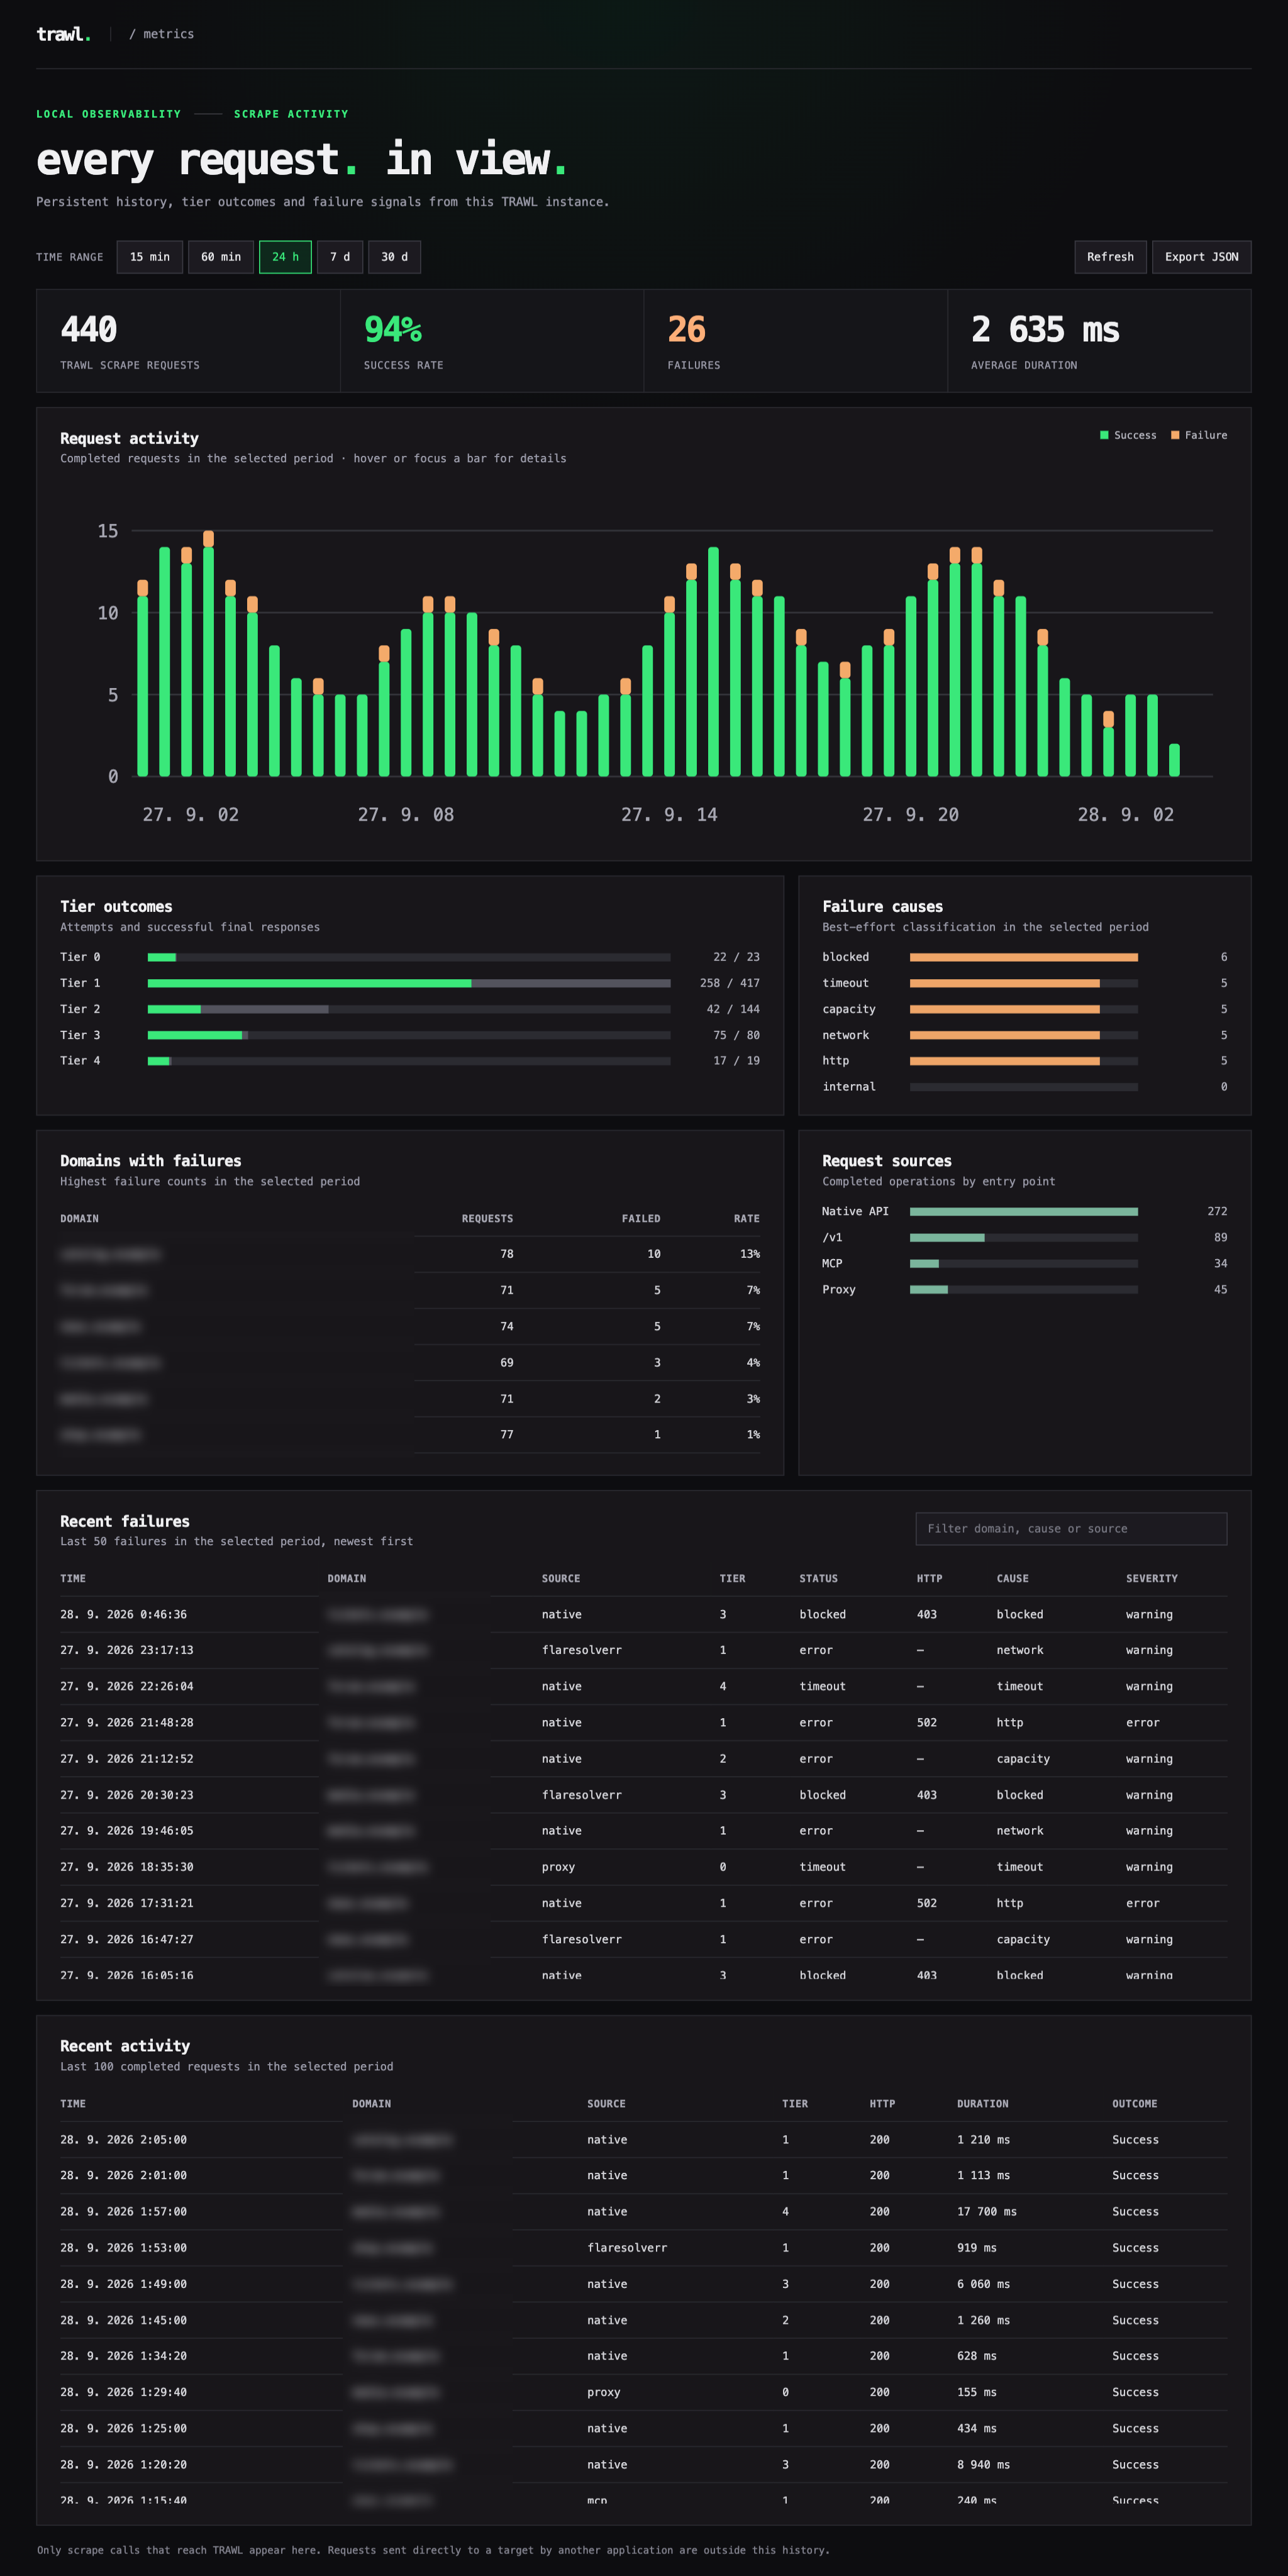
Illustrative traffic. Your dashboard shows requests handled by your own instance.
Dashboard setup and metrics ↗Run v1.11.0 with MCP enabled and persistent dashboard history. Pull the image, wait for /health, then send your first request.
services:
  trawl:
    image: ghcr.io/germondai/trawl:1.11.0
    ports: ["127.0.0.1:8191:8191"]
    shm_size: 1gb
    environment:
      SESSION_CACHE_DRIVER: memory
      BROWSER_POOL_SIZE: 1
      METRICS_DASHBOARD_ENABLED: "true"
      MCP_ENABLED: "true"
    volumes: [trawl_metrics:/data/metrics]
    restart: unless-stopped
volumes:
  trawl_metrics:
For older CPUs or NAS deployments, use :1.11.0-baseline. Heavy pages and extra sessions may need more memory. same commands, different runtime.
Dashboard: http://localhost:8191/dashboard. MCP: http://localhost:8191/mcp. Start commands expose the API on localhost; other containers can use http://trawl:8191 on the same Docker network.
docker compose up -dAPI usage
# Native scraping API
curl -s -X POST http://localhost:8191/scrape \
  -H "Content-Type: application/json" \
  -d '{"url":"https://nopecha.com/demo/cloudflare","maxTimeout":60000}' | jq '{tier,totalMs}'

# FlareSolverr-compatible request
curl -s -X POST http://localhost:8191/v1 \
  -H "Content-Type: application/json" \
  -d '{
    "cmd": "request.get",
    "url": "https://nopecha.com/demo/cloudflare",
    "maxTimeout": 60000
  }' | jq '.solution.response'